In many SQL Server environments, SQL Server blocking and concurrency problems do not start with dramatic infrastructure metrics. CPU usage looks normal, memory does not show obvious pressure, and storage latency stays within the expected range. From an infrastructure perspective, the server appears calm. At the same time, users wait, jobs take longer than usual, and the application starts reporting timeouts.
That mismatch can mislead troubleshooting teams very quickly. It is tempting to assume that a system with enough CPU, enough memory, and acceptable I/O latency cannot have a serious performance problem. In practice, that view is too narrow. SQL Server performance is not only about how quickly the engine can execute work. It is also about whether sessions can continue their work at all.
Some production problems do not come from a lack of processor power. They come from sessions waiting on other sessions, transactions holding locks longer than expected, or workloads meeting each other at the wrong time. A reporting query may touch hot tables during write activity. A batch process may run during business hours. A small application change may increase transaction duration without looking like a database change at first glance.
In those cases, the server may not be busy in the way a dashboard suggests. It may have capacity left, but the workload still cannot move through the system freely because sessions wait behind each other.
SQL Server blocking and concurrency can hide behind calm CPU metrics
CPU is an important signal, but it is not a diagnosis by itself. High CPU can explain poor response times when SQL Server spends too much processor time compiling, scanning, sorting, joining, or executing inefficient queries. Low or moderate CPU only tells you that processor time is probably not the current limiting factor.
A session waiting on a lock does not need much CPU while it waits. The session may be unable to continue, while the server still looks calm from the outside. This is why SQL Server blocking and concurrency problems often confuse teams that mainly look at infrastructure metrics. The application feels slow, users see timeouts, and jobs miss their expected windows. The classic resource graphs still do not show the kind of pressure people expect when a system is in trouble.
In my work, I treat that mismatch as useful information, not as reassurance. If the system is slow and CPU looks fine, the next question is not whether SQL Server has enough power. The better question is what the workload is waiting for.
SQL Server blocking is normal until it becomes operationally relevant
Blocking itself is not unusual in SQL Server. SQL Server uses locks to protect consistency. When one session changes data, the engine may need to prevent another session from reading or changing the same data in an incompatible way. The exact behavior depends on the isolation level and the operation involved.
Microsoft describes blocking as a normal lock-based concurrency behavior where one session holds a lock on a resource and another session waits for a conflicting lock on the same resource.
Short blocking is part of normal database activity. A transaction changes data, holds locks briefly, commits, and other sessions continue. In a healthy workload this happens constantly without anyone noticing. The problem starts when blocking becomes long, frequent, unpredictable, or important for the business process waiting behind it.
At that point, raw execution speed no longer limits performance. The order in which sessions can continue becomes the limiting factor. This distinction matters because the visible slow query does not always cause the problem. A query may run slowly because its execution plan is poor, but it may also run slowly because it waits behind another session. The query in the timeout message may only show where the pain becomes visible.
A common production pattern
A typical example is a reporting query that times out during business hours. On its own, the query may be acceptable and may normally finish quickly enough. At that point in time, however, it touches data that another session changes. The report becomes the visible failure, while the more important question is why the other session holds locks long enough to block it.
That other session may run an update with a wider lock footprint than expected. It may sit inside an explicit transaction, scan too much data because an index is missing or unsuitable, or keep the transaction open while the application performs work outside the database. In a customer system, this distinction often decides whether the team fixes a visible timeout or the process that keeps producing it.
That is why tuning the blocked query first can distract from the real issue. Blocking is a relationship. To understand it properly, you need to understand both sides.
Wait stats show direction, not the whole story
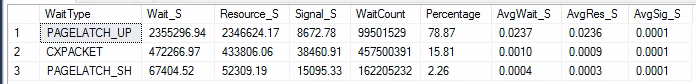
This is where wait stats become useful, but also easy to overread. They move the investigation away from guessing because they show where SQL Server tasks spent time waiting. In practice, that is often more useful than starting and ending with CPU charts. It is still only the beginning of the investigation.
This continues the same diagnostic idea from the earlier article on SQL Server wait statistics: waits are useful because they show where SQL Server spends time, but they still need context.
For SQL Server blocking and concurrency problems, that context is critical. Instance-level waits can show that lock waits matter, and wait types such as LCK_M_* can point toward lock-related waiting. But this information is still aggregated. It does not tell you which session blocked others, which business process was active, whether the pattern is current or historical, or whether those waits are expected for that workload.
From aggregated waits to blocking relationships
Even when the top waits are not lock waits, an aggregated view can still help because it shows where time was spent. But it does not show the session relationship behind a blocking problem. For that, the investigation has to move from aggregated waiting to concrete relationships. You need to know which session waits, which session blocks it, whether a head blocker exists, whether an open transaction is involved, how long the transaction has been active, what query runs, and what resource the session waits on.
Those details bring the analysis closer to the system that users experience. Without that step, wait stats can become another set of technical numbers that look useful but still leave the operational cause untouched. For blocking problems, the relevant question is not only that SQL Server waited. The relevant question is which session waited, which session caused the wait, and why that relationship appeared at that time.
In SQL Server blocking, the blocked session is often the victim
When users report slowness, the visible query is often the one that failed, timed out, or appeared in monitoring. That makes it tempting to tune that query immediately. Sometimes that is the right path. In blocking scenarios, however, it is often only part of the story.

The blocked session may have a reasonable execution plan, use the expected indexes, and normally finish in an acceptable time. Its runtime is poor because it waits, not because the query itself is the main problem. If one session holds locks that many other sessions need, the blocked sessions are symptoms. The better starting point is the blocker.
The blocker may run longer than expected, touch more rows than intended, hold an open transaction, or sit in an application workflow that keeps database locks alive while something else happens outside SQL Server. This is a common place where the technical and operational views have to meet. SQL Server can show the blocking chain, the waiting requests, the blocking session, and the transaction state. But SQL Server may not explain why the application holds a transaction open, why a job runs during business activity, or why a process changed after a deployment.
This is why the context around the blocker matters more than the timeout message alone. You often do not fix a blocking problem by looking only at the blocked query. You fix it by understanding why the blocking session can hold up the workload for that long.
More hardware does not fix a bad concurrency pattern
Adding CPU can help when CPU is the limiting factor. It does not make a session release a lock earlier if transaction duration, application behavior, inefficient access patterns, or the wrong workload timing hold that lock open.
More memory can reduce physical reads, and faster storage can reduce I/O latency. Both can improve many SQL Server workloads. But neither one changes the basic concurrency relationship between sessions that need incompatible access to the same data at the same time.
This does not mean infrastructure is irrelevant. It means infrastructure should not replace diagnosis. In some environments, more capacity may reduce the symptoms for a while because queries finish faster, locks stay active for a shorter time, and blocking becomes less visible. If the underlying pattern remains, it usually returns when data volume grows, user activity increases, or reporting and operational workloads start to overlap again.
That is why “more CPU” is a weak answer when the actual problem is transaction design, lock footprint, or workload timing. Before changing capacity, it is worth understanding what kind of waiting occurs. CPU pressure, lock waits, memory grants, I/O waits, latching, parallelism, and transaction log pressure lead to different investigations. Treating all slowness as the same category is where many troubleshooting efforts lose time.
A useful investigation connects technical evidence with business timing
In a production system, a blocking investigation should not stop at one DMV output or one monitoring screenshot. It starts with the symptom, such as slow response times, timeouts, delayed jobs, or blocked sessions. Then it checks whether the issue is current, recurring, or historical. A useful investigation looks at waits, but then follows them into sessions, locks, requests, queries, transaction duration, application timing, and job schedules.
This is the same distinction I described in the article about visible symptoms and possible root causes: the symptom is where the investigation starts, not where it should stop.
Patterns matter more than isolated snapshots. One blocked session at a random moment may not mean much. A recurring head blocker during business hours does. A nightly batch process that blocks order entry is relevant. So is a transaction that regularly holds locks while the application performs non-database work, or a report that collides with write activity every morning.
Be careful with quick fixes
This is where I would be careful with quick fixes. NOLOCK may hide blocking symptoms while introducing data consistency problems. Read Committed Snapshot Isolation may be a valid design option, but it is still a design decision, not a switch to flip blindly. Index changes may reduce lock duration, but only if the access pattern is actually part of the problem.
For that reason, isolation levels and row versioning should be treated as transaction design decisions, not as generic performance switches.
The useful fix depends on what the evidence says about timing, transaction scope, access patterns, and the sessions involved. Sometimes the answer is query tuning. Sometimes it is an index change, transaction redesign, or a cleaner separation between reporting and operational workloads. In other cases, a job has to move, or the application needs to change how long it keeps a transaction open. In production systems, the useful change is rarely the one that sounds most convenient. It is the one that reduces the waiting pattern without creating a larger operational risk somewhere else.
A better way to think about SQL Server performance
For SQL Server blocking and concurrency problems, I find it more useful to think in terms of throughput and waiting, not just resource usage. SQL Server may execute the work efficiently once it can start. That does not help much if sessions cannot access the data they need for too long.
The useful questions are less about one metric and more about the shape of the workload. Are transactions short and clear enough for the way the system is used? Do reporting, maintenance, and operational activity collide? Do the observed waits point to resource pressure, poor design, or normal workload behavior under load?
These questions take more work than looking at a CPU chart, but they are usually closer to the way SQL Server behaves in production. For DBAs, this creates a more reliable troubleshooting path. For sysadmins, it explains why infrastructure metrics can look fine while users still experience delays. For technical leadership, it makes the risk clearer because the issue may not come from a lack of server capacity. It may come from lost throughput because work waits behind other work.
That changes the conversation. The decision is no longer simply whether the server needs more resources. The decision becomes whether the workload, transaction design, indexing strategy, isolation behavior, and operational timing still fit the way the system is used.
Conclusion: SQL Server blocking and concurrency affect throughput
“CPU is fine” is useful information. It is not a performance diagnosis.
SQL Server blocking and concurrency problems live between sessions. They are not always visible as resource exhaustion. They often show up in the uncomfortable gap between calm server metrics and a workload that no longer moves properly.
That is why SQL Server performance work has to connect infrastructure metrics with database evidence and business timing. Otherwise, the investigation may explain that the server has capacity left, but still miss why the workload is waiting.
The practical question is not only whether SQL Server has enough power to do the work. It is whether the workload can move through the system without unnecessary waiting. For production systems, that difference is often where the real performance problem begins.
Comments are closed.